Claude Opus 5.5 Tops Mazur Constrained Story Writing Benchmark
Anthropic’s Claude Opus 5.5 scored 1.00 on the 50-task sample at $0.0242 per task. OpenAI’s GPT-6 Astra and GPT-6.1 Sol Pro tied for second at 0.99, with Sol Pro costing $0.0121 per task.
By Ryan Merket · Published
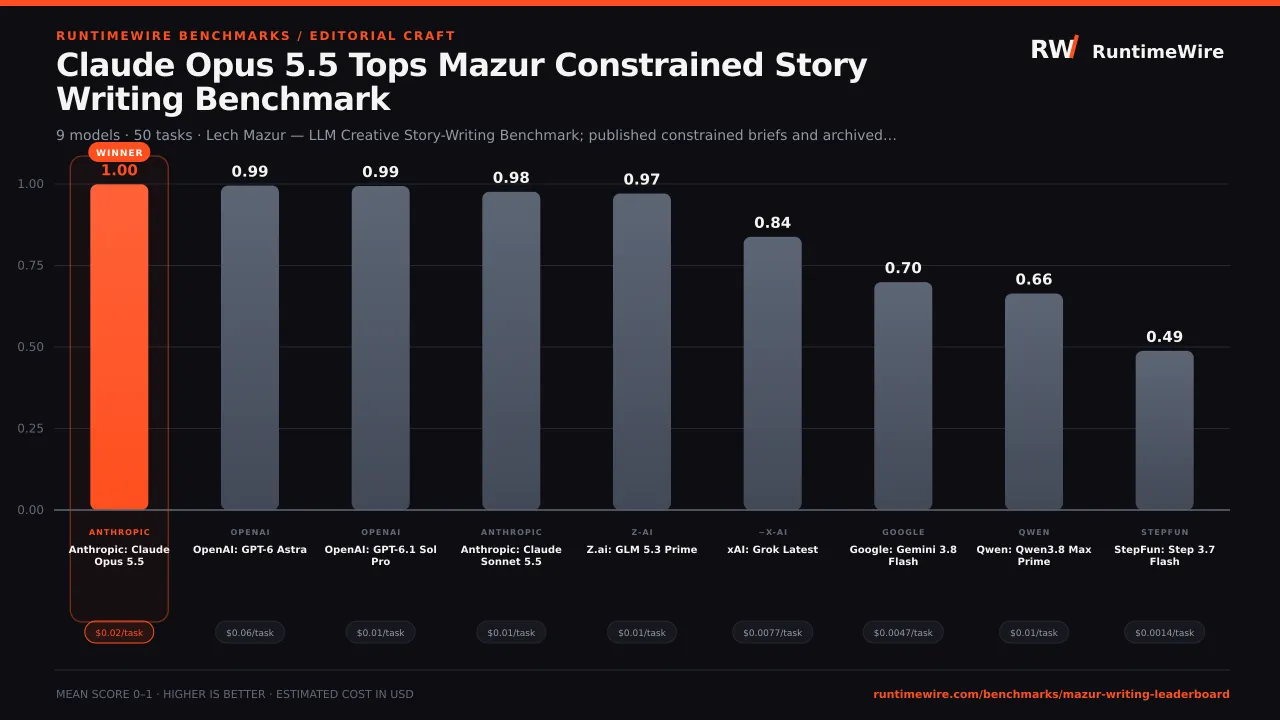
Leaderboard
| Rank | Model | Mean score | Est. cost/task |
|---|---|---|---|
| 1 | Anthropic: Claude Opus 5.5 | 1.00 | $0.0242 |
| 2 | OpenAI: GPT-6 Astra | 0.99 | $0.0599 |
| 3 | OpenAI: GPT-6.1 Sol Pro | 0.99 | $0.0121 |
| 4 | Anthropic: Claude Sonnet 5.5 | 0.98 | $0.0106 |
| 5 | Z.ai: GLM 5.3 Prime | 0.97 | $0.0111 |
| 6 | xAI: Grok Latest | 0.84 | $0.0077 |
| 7 | Google: Gemini 3.8 Flash | 0.70 | $0.0047 |
| 8 | Qwen: Qwen3.8 Max Prime | 0.66 | $0.0141 |
| 9 | StepFun: Step 3.7 Flash | 0.49 | $0.0014 |
How we scored it
Every model answered the same 50-task battery from Mazur Constrained Story Writing (50-task sample) (Lech Mazur — LLM Creative Story-Writing Benchmark; published constrained briefs and archived V4 grading protocol), one task at a time, with no tools and no retries on content.
50 open-ended tasks were graded 0–10 by OpenAI: GPT-5.6 Sol Pro against a fixed rubric — blind to which model wrote the answer — and normalized to the same 0–1 scale.
Reasoning effort was pinned to max for every model whose lane exposes a control (OpenAI-style reasoning_effort, Anthropic extended thinking, Gemini thinking config). Models marked vendor default on the interactive board expose no such control and ran as shipped.
A model's mean score averages its graded tasks; a generation failure counts as 0. Cost per task is estimated from each model's published per-token pricing ("—" where pricing isn't public), so treat it as directional, not billing-exact.
Grading could not be completed for every task on 9 models; their means cover the graded subset.
Explore every prompt, answer, and per-task grade in the interactive leaderboard.