DeepSpeed's cost-based prefill buckets halve latency on a long-tail Qwen batch
An opt-in planner for Microsoft's DeepSpeed project cut latency from 1.68 to 0.84 seconds on a skewed Qwen batch in a contributor's single-GPU FP32 test.
By RuntimeWire Staff · Published
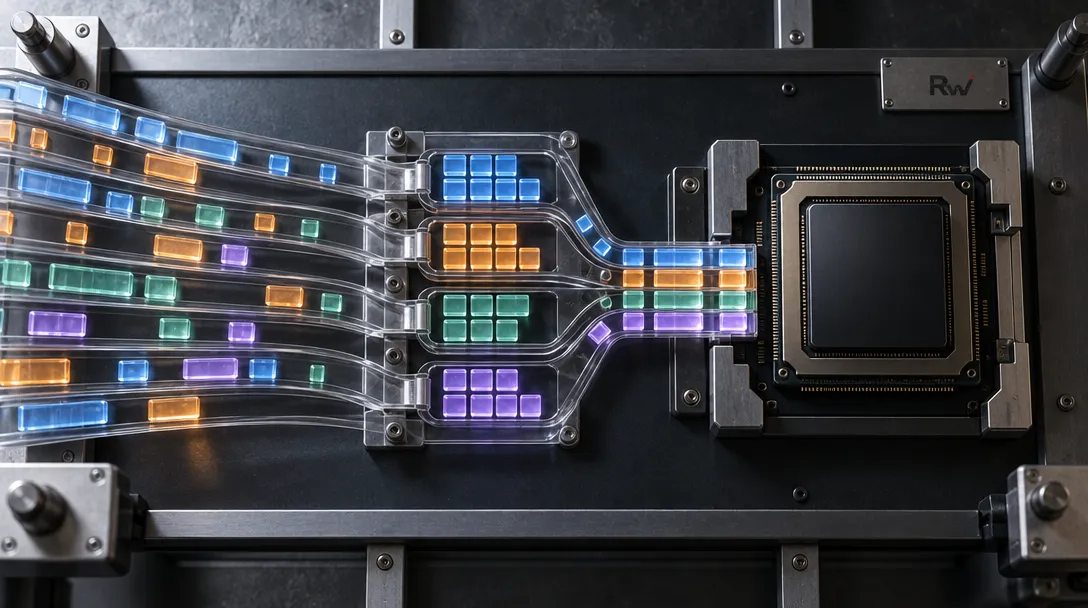
An opt-in planner for Microsoft's DeepSpeed project cut latency from 1.68 to 0.84 seconds on a skewed Qwen batch in a contributor's single-GPU FP32 test.