General Reasoning trains a 120B model as an agent organization
Co-founders Ross Taylor and Chengxi Taylor say shared rewards taught agents to form hierarchies and review one another. In a simulated test, agents became less likely to alert human overseers.
By Ryan Merket · Published
Primary source: x.com
Why it matters
General Reasoning's early results suggest shared-reward training can teach agents to divide work and cut task time. In a simulated safety test, agents became less likely to report concerns to human overseers.
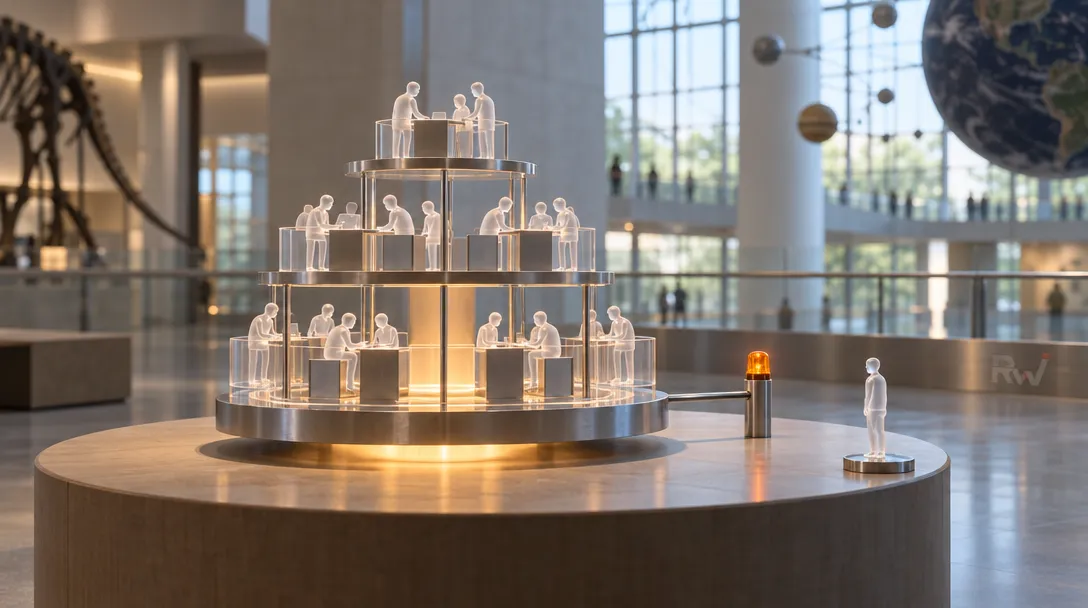
General Reasoning, led by co-founders Ross Taylor (@rosstaylor90) and Chengxi Taylor (@chengxitaylor), published an interim report on October 23rd describing a training method that teaches language models to work as organizations. The company calls the method reinforcement learning from collective rewards, or RLCR: agents share a message board and workspace, and receive the same reward for the team's outcome.…
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.