Meta says Prometheus delivered 85% goodput training Muse Wonder
The Ohio cluster's first phase trained Muse Wonder; Meta says firmware fixes have since raised its interruption interval beyond 54,000 GPU-hours.
By Ryan Merket · Published
Primary source: X
Why it matters
The self-reported figures put reliability alongside GPU scale in Meta's frontier-model strategy and show the operational bottleneck it is trying to address as it builds toward a roughly 1 million-GPU cluster.
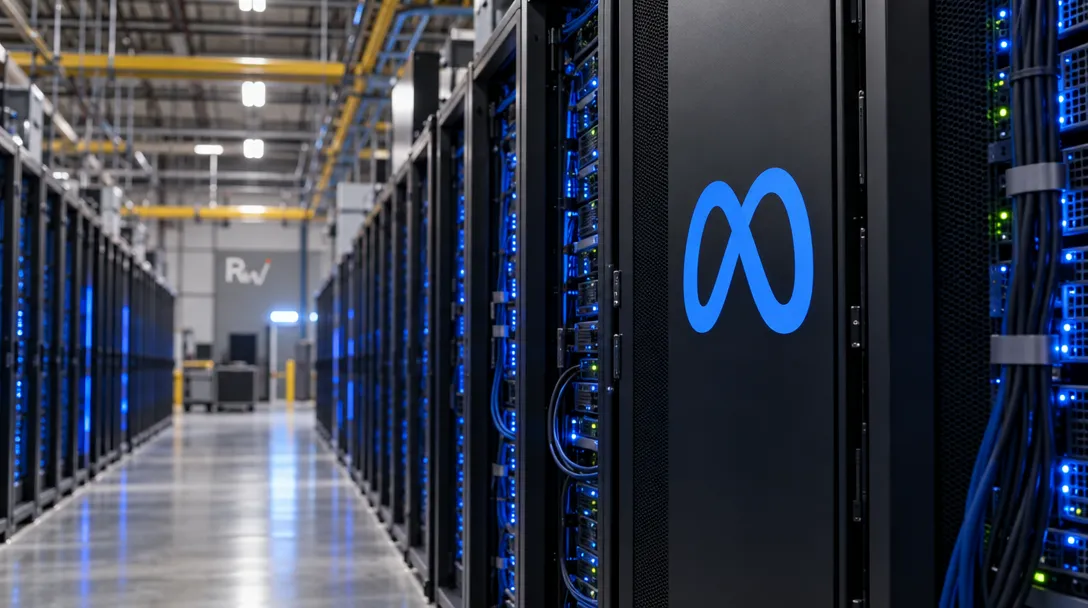
Meta says its Prometheus supercluster in New Albany, Ohio, delivered more than 85% goodput during Muse Wonder pretraining and more than 90% during reinforcement learning. AI at Meta said in an October 19th post on X that the first phase of Prometheus trained Muse models, including Muse Wonder.…
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.