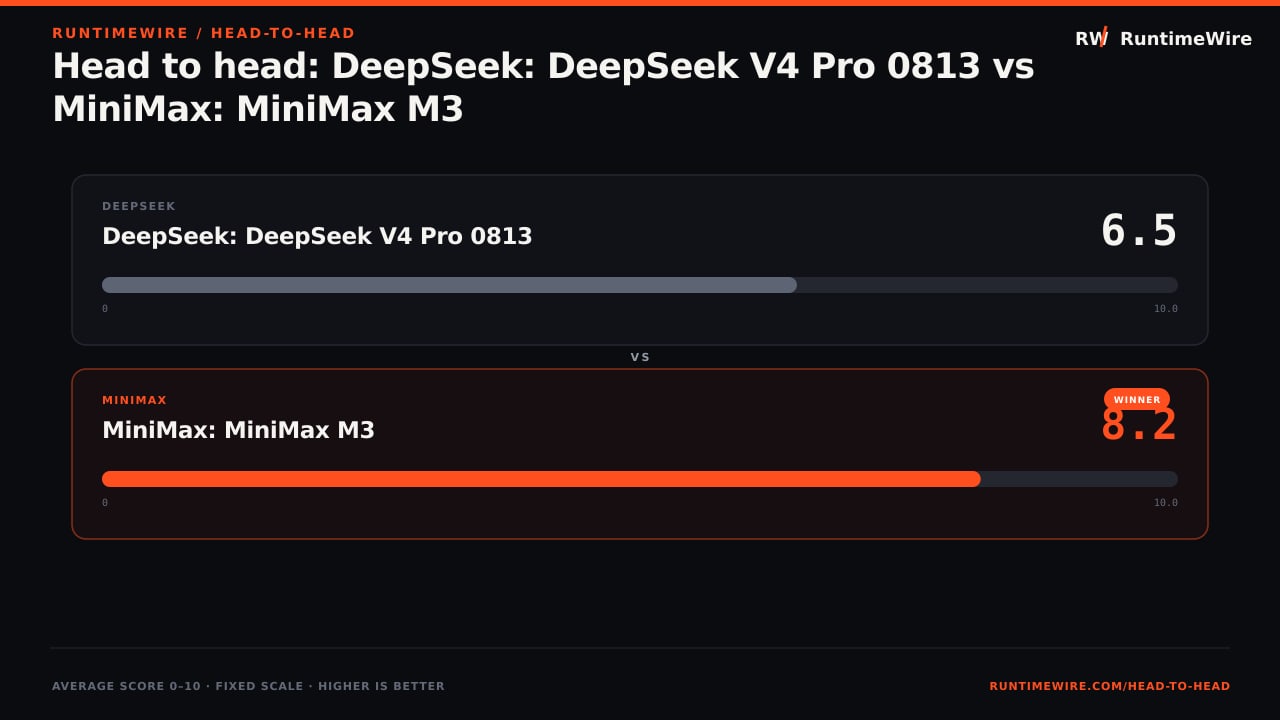
DeepSeek V4 Pro 0813 and MiniMax M3 face off on reporting judgment, narrative craft, and exacting editorial constraints. The comparison tests not just fluency, but how reliably each model handles facts, structure, and length requirements.
MiniMax M3 takes the saved verdict, with an aggregate score of **98.0** to DeepSeek V4 Pro 0813’s **77.5**. It won **9** of the 12 tasks, while DeepSeek won **1** and **2** were ties. This is a decisive result on this task sample—not a claim about statistical confidence or performance beyond it.
MiniMax’s advantage was most visible in reported-story work. It more accurately handled chronology and news judgment, and generally did a better job meeting length and formatting requirements. Its publication-ready edit also stayed closer to the supplied reporting. DeepSeek, by contrast, sometimes introduced precise details or claims the source material did not support.
The win is not a clean sweep of editorial quality. Both models added unsupported details in several writing tasks, and MiniMax’s outputs were not immune: judges flagged speculation and invented specifics in some of its stories. DeepSeek’s lone task win came on weaving quotes into a narrative, where it used them more selectively and stayed closer to the brief. The models tied on selecting the accurate lede and preserving an exact final-draft structure.
**Final call: MiniMax M3 wins this head-to-head on stronger performance across the saved tasks, especially factual discipline and execution of constraints.** DeepSeek showed a notable strength in quote handling, but it did not offset MiniMax’s broader advantage in this sample.
News judgment in the opening
Write only the opening of this news story: an H1 headline, an italicized dek and three to five paragraphs totaling 180–250 words.
The opening must establish what happened, quantify the scope, explain why it matters and carefully distinguish confirmed facts from unknowns. It should pull the reader forward without sensationalizing the incident.
Reporting:
* Cloudnote discovered that a debugging page containing customer prompt excerpts was accessible without authentication.
* The page was exposed for four hours on Monday.
* Logs show excerpts from 1,842 user sessions.
* The excerpts could include up to 200 characters from a prompt.
* Cloudnote removed the page 19 minutes after a researcher notified it.
* The company says it has found no evidence that anyone besides the researcher accessed the page.
* It has not completed its investigation.
* Full documents, passwords and payment information were stored elsewhere and were not present on the page.
* Cloudnote has 3.2 million registered users.
DeepSeek: DeepSeek V4 Pro 0813: # Cloudnote Confirms Debug Page Exposed Snippets of 1,842 User Prompts
*The note-taking and AI assistant platform said the unauthenticated endpoint was live for four hours before being removed on Monday.*
Cloudnote disclosed Tuesday that a diagnostic web page containing excerpts of customer prompts was publicly accessible without a password for approximately four hours earlier this week. According to the company, internal telemetry showed the page was reachable from 14:02 to 18:11 UTC on Monday, and was removed 19 minutes after an independent security researcher reported the exposure.
The company said logs indicate the page contained text fragments from 1,842 distinct user sessions. Each excerpt could include up to 200 characters of a user’s prompt, though Cloudnote emphasized that the snippets were truncated and did not include complete conversations. Full documents, account passwords, and payment card details were stored in separate systems and were not present on the exposed page, the company stated.
Cloudnote, which reports 3.2 million registered users, said its initial review found no evidence that anyone other than the reporting researcher accessed the page during the exposure window. However, the company cautioned that its investigation is not yet complete and that access logs do not always provide definitive proof of who viewed a resource.
The incident is likely to raise questions about Cloudnote’s security practices and the sensitivity of AI prompt data. The company said it has disabled the debugging endpoint and is reviewing its internal monitoring procedures. It has not yet said whether it will notify affected users or regulators.
MiniMax: MiniMax M3: # Cloudnote Exposed Excerpts From 1,842 User Prompts on Unauthenticated Debug Page
*The note-taking platform says an internal page was left accessible for four hours on Monday before being removed.*
A debugging page on Cloudnote was accessible without authentication for roughly four hours on Monday, exposing short excerpts of user prompts before the company removed it, according to the company and the security researcher who reported the issue.
The exposed page contained fragments from 1,842 user sessions, with each excerpt capped at 200 characters of a prompt, Cloudnote said. The company has 3.2 million registered users, meaning the exposure touched a small share of accounts, though the substance of those prompts varied by user.
Cloudnote took the page down 19 minutes after being notified by the outside researcher. The company said it has found no evidence that anyone other than the researcher accessed it during the window, though it cautioned that its investigation remains incomplete.
Several details remain unconfirmed. It is not yet clear whether the exposure stemmed from a misconfiguration or a code change, and the company has not released the excerpts themselves or announced plans to notify affected users individually.
More sensitive material, including full documents, account passwords and payment information, is stored in separate systems and was not present on the exposed page, Cloudnote said. Even so, the episode illustrates how internal development tools can create privacy exposure when they surface fragments of what users typed.
OpenAI: GPT-6 Luna: Model B is more careful about the distinction between accessibility and confirmed access, while Model A invents precise exposure times and additional company actions not in the reporting. Model B also adds unsupported details, including that the exposure affected a small share of accounts, but its opening is more disciplined overall. (Second judge pass, order swapped — scores are the average of both: Model B better preserves the reported facts and clearly marks what remains unknown, though it ad | Anthropic: Claude Fable 5.1: Model A fabricates specifics not in the reporti…
Chronology with narrative momentum
Turn the scrambled reporting below into a 450–600-word Markdown news article.
Choose an opening that captures the consequence of the failure, then reconstruct the sequence clearly. Preserve the chronology without producing a minute-by-minute incident log. Give technical details enough context for a general reader.
Reporting:
* KiteBridge makes expense-management software.
* At 8:45 a.m. Tuesday, it deployed version 4.2.
* The first customer complaint arrived at 9:12 a.m.
* A payment-processor timeout caused KiteBridge’s fallback system to treat retries as new reimbursement requests.
* The software generated 13,400 duplicate reimbursements totaling $2.8 million.
* KiteBridge suspended automated payments at 10:03 a.m.
* Ninety-one corporate customers were affected.
* By Wednesday evening, $2.3 million had been recovered. The rest remained pending.
* No employees had money withdrawn from their accounts; employers funded the duplicate payments.
* An April changelog said version 4.0 had introduced “exactly-once payment protection.”
* KiteBridge’s public incident page initially described the problem as delayed reimbursements.
* The incident page first disclosed the duplicate payments six hours after automation was suspended.
* CEO Lena Ortiz apologized and said the company would publish a technical report.
DeepSeek: DeepSeek V4 Pro 0813: KiteBridge’s promise of “exactly-once” payments collapsed within half an hour on Tuesday, when a routine software update triggered a cascade of duplicate reimbursements that sent $2.8 million in unintended corporate funds to employees across 91 companies. The failure has raised sharp questions about the expense-software maker’s payment safeguards and the transparency of its public incident reporting.
The trouble began at 8:45 a.m., when KiteBridge deployed version 4.2 of its expense-management platform. The release was intended to improve payment handling, but it instead exposed a fragile fallback mechanism. When a payment processor timed out, KiteBridge’s system treated each automatic retry as a fresh reimbursement request rather than recognizing the original transaction as still in progress. The result was a flood of duplicate payments.
The first customer complaint arrived at 9:12 a.m., less than half an hour after deployment. Over the next several hours, KiteBridge generated 13,400 duplicate reimbursements. Unlike some payment failures, however, employees did not have money clawed back from personal accounts. The duplicate payments were funded by the employers themselves, meaning KiteBridge’s corporate customers were left waiting to recover money that should never have left their accounts.
KiteBridge suspended automated payments at 10:03 a.m., roughly 78 minutes after the first signs of trouble. By then, the damage was extensive. Ninety-one corporate customers were affected, ranging from mid-market firms to larger enterprises that rely on KiteBridge to process routine employee expenses.
The company’s public messaging compounded the problem. KiteBridge’s incident page initially described the issue only as delayed reimbursements, a characterization that downplayed the scale and nature of the failure. It was not until six hours after automation was suspended that the page first disclosed the duplicate payments. For affected finance teams, that gap meant hours of confusion as they attempted to reconcile accounts without understanding why balances were shifting.
By Wednesday evening, KiteBridge said $2.3 million had been recovered. The remaining $500,000 was still pending, leaving some corporate customers waiting to see whether their funds would be fully returned.
The incident has drawn particular scrutiny because of KiteBridge’s earlier technical claims. An April changelog for version 4.0 stated that the platform had introduced “exactly-once payment protection,” a term that implies the system would prevent duplicate transactions. Tuesday’s failure suggests that protection failed under a relatively common condition: a payment-processor timeout.
CEO Lena Ortiz apologized for the disruption and said the company would publish a full technical report. She did not specify a timeline for the report’s release.
For KiteBridge, the challenge now is twofold. The company must recover the remaining funds and repair its payment-retry logic, but it also faces a credibility problem. Customers who rely on expense software to handle money correctly may be less willing to accept assurances that the failure was an isolated event, especially when the company’s first public account of the incident omitted the very error that mattered most.
MiniMax: MiniMax M3: # Software Bug Triggers $2.8 Million in Duplicate Expense Reimbursements at KiteBridge
A faulty software update from expense-management firm KiteBridge caused the platform to issue 13,400 duplicate reimbursements totaling $2.8 million to employees of 91 corporate customers, the company confirmed this week. By Wednesday evening, roughly $2.3 million had been recovered; the remainder remained pending as the company worked to unwind the mistaken transactions.
The trouble began shortly after KiteBridge deployed version 4.2 of its platform at 8:45 a.m. Tuesday. Within half an hour, the first customer complaint rolled in at 9:12 a.m. According to the company, the root cause was a payment-processor timeout: when KiteBridge's systems tried to send funds to reimbursement recipients, the external processor occasionally failed to respond within the expected window. The platform's fallback mechanism, designed to ensure transactions eventually complete, misinterpreted those timeouts and treated each automatic retry as a brand-new reimbursement request rather than a continuation of the original one. The result was that thousands of legitimate payments were effectively doubled — in some cases more.
The duplicate transactions were drawn from employer-funded corporate accounts, not from the personal bank accounts of the employees receiving reimbursements. Company officials emphasized that no individual worker saw money withdrawn from their own pockets. Still, the corporate customers were left reconciling inflated expense ledgers and racing to halt further disbursements.
KiteBridge suspended automated payments at 10:03 a.m., roughly an hour and fifteen minutes after deployment. That decision stopped the bleeding, but the company's public communications lagged behind. The incident page initially characterized the problem as "delayed reimbursements," a phrasing that understated the scale of the issue. It was not until roughly six hours after automation was suspended — late Tuesday afternoon — that the page acknowledged the duplicate payments in plain terms.
The episode is particularly awkward given KiteBridge's own marketing. An April changelog announced that version 4.0 had introduced what the company described as "exactly-once payment protection," a technical guarantee that a single transaction would be processed only one time, no matter how many times a system attempted to send it. Tuesday's failure suggests that guarantee broke down under real-world conditions, precisely when the safety mechanism was most needed.
CEO Lena Ortiz issued an apology and pledged to publish a full technical report on the incident. She did not specify a timeline for that report, though she acknowledged the company owed customers a candid account of how a feature marketed as a safeguard failed so dramatically.
For affected corporate customers, the practical work continues. Employers are now tasked with identifying which reimbursements were duplicated, recovering the excess funds, and reassuring employees whose expense reports briefly showed inflated payouts. KiteBridge has not yet said whether the affected employers will be compensated for the administrative burden, nor has it detailed what changes to version 4.2 or its retry logic will accompany any future release.
The incident underscores a recurring lesson in financial software: even when a company builds redundancy to protect transactions, that redundancy itself can become a source of error if it is not rigorously tested against the specific failure modes it is meant to defend against. KiteBridge's Tuesday morning deployment will likely be studied by engineers and product teams across the industry for months to come.
OpenAI: GPT-6 Luna: Model B reconstructs the sequence more accurately and explains the retry failure clearly for general readers. Model A has a misleading timeline, while both add some details not present in the reporting; Model B’s extra speculation keeps it from scoring higher. (Second judge pass, order swapped — scores are the average of both: Model B preserves the timeline more accurately; Model A says suspension came 78 minutes after the first signs of trouble, though it was 51 minutes after the first complain | Anthropic: Claude Fable 5.1: Model B delivers a proper Markdown headline, a…
Select the strongest accurate lede
Based only on the facts below, select the strongest news lede. Respond with one letter.
Facts:
* ByteBarge pulled its $12-per-month AI assistant on Tuesday.
* Private workspace titles from 4,860 accounts were sent to a publicly accessible analytics endpoint.
* The exposure lasted 11 hours.
* Message contents were not sent.
* The company has found no evidence of malicious access.
A. ByteBarge users suffered a massive privacy disaster Tuesday when the company leaked their private messages online.
B. ByteBarge, an innovative collaboration company, made the difficult decision to cancel one of its products.
C. ByteBarge pulled its $12-per-month AI assistant Tuesday after discovering that private workspace titles from 4,860 accounts had been sent to a public analytics endpoint for 11 hours.
D. Thousands of ByteBarge users woke Tuesday to learn that everything they had written was visible to hackers.
DeepSeek: DeepSeek V4 Pro 0813: C
MiniMax: MiniMax M3: C
Scored against the benchmark's reference answer (choice match): Model A was correct, Model B was correct.
Numbers shaped into a story
Write a 600–750-word Markdown article from the benchmark results below.
Build the story around the clearest finding. Explain the methodology and limitations where readers need them. Avoid reciting the table row by row or treating small differences as decisive.
Benchmark:
* Researchers tested five language models on 200 anonymized customer-support tickets.
* Each model produced one proposed answer per ticket.
* Three experienced support managers graded the answers blindly.
* Scores combined factual correctness, usefulness and tone.
* Model North: 84.2 average score; $1.90 estimated cost per 1,000 tickets.
* Model Vale: 83.8; $0.74 per 1,000 tickets.
* Model Ember: 79.1; $0.31 per 1,000 tickets.
* Model Kite: 76.4; $0.22 per 1,000 tickets.
* Model Harbor: 71.0; $0.08 per 1,000 tickets.
* North and Vale’s score difference was not statistically significant.
* Vale answered 18% faster than North.
* North performed best on billing disputes.
* Vale performed best on technical troubleshooting.
* All five models performed poorly when a ticket depended on an image attachment.
* The test used English-language tickets from one software company.
* Researchers did not test agentic actions, tool use or multilingual support.
DeepSeek: DeepSeek V4 Pro 0813: Here is a Markdown article based on the benchmark results, structured around the key finding regarding the price-performance sweet spot.
---
# The Law of Diminishing Returns: What Happens When AI Models Meet Customer Support
In the race to integrate artificial intelligence into customer service, the assumption is often "bigger is better." The logic follows that the most expensive, most powerful language model on the market will naturally yield the highest satisfaction rates and the most accurate answers.
However, a new benchmark analysis of five leading language models suggests that when it comes to handling real-world support tickets, price and performance do not move in lockstep. The study reveals a classic case of diminishing returns: while the most expensive model does edge out the competition in raw quality, a mid-tier model delivers statistically identical results for a fraction of the cost.
### The $1.16 Question
The study, which evaluated five distinct language models on a dataset of 200 anonymized customer-support tickets, painted a clear picture of a plateau at the top of the market.
Graders (three experienced support managers) assessed the models—codenamed North, Vale, Ember, Kite, and Harbor—based on factual correctness, usefulness, and tone.
At first glance, **North** appeared to be the winner. It achieved an average score of 84.2, the highest in the test. However, that lead evaporated upon closer statistical inspection. The performance of **Vale**, which scored 83.8, was deemed not statistically significant from North’s. In practical terms, they are effectively in a dead heat on quality.
The difference, however, lies in the balance sheet. North costs an estimated $1.90 per 1,000 tickets. Vale costs $0.74 per 1,000 tickets. That is a 61% cost reduction for a 0.4-point dip in quality that statisticians consider noise.
But the plot thickens when speed is factored in. Vale answered queries 18% faster than North. For operations managers, this creates a rare "win-win" scenario: Vale is both cheaper *and* faster, without sacrificing the quality of the response.
### Bang for the Buck Down the Ladder
The cost-performance curve continues to bend as we move down the pricing tiers.
**Ember** ($0.31 per 1,000 tickets) scored 79.1. While that is roughly five points behind the leaders, it represents a potential "budget" option. If a support team is handling low-stakes queries where a 79% success rate is acceptable—perhaps simple password resets or FAQ lookups—Ember offers a drastic cost reduction of nearly 84% compared to North.
The trend fails at the bottom end, however, illustrating that there is a floor for quality.
**Kite** ($0.22) and **Harbor** ($0.08) are exceptionally cheap. **Harbor** in particular is nearly 24 times cheaper than North. Yet the scores tell a story of unusable responses. At 71.0, Harbor’s responses were likely riddled with mistakes or tonal issues, and Kite’s 76.4 suggests it struggles with the nuance of frustrated customers. The researchers found that while these models can speak English, they likely failed at the "support" part of customer support. For a production environment, saving eight cents is not worth the cost of losing a customer.
### Context is King: Specialization Matters
While the aggregate scores suggest a tie between North and Vale, the research revealed that these models possess distinct personalities and competencies when looking at specific ticket categories.
The data showed that **North** performed best on **billing disputes**. This is a significant finding. Billing disputes often involve complex policy adherence, calculation, and strict compliance language. If a company deals with high-value transactions or frequent payment issues, the premium price tag of North might be justified for that specific routing segment.
Conversely, **Vale** performed best on **technical troubleshooting**. Technical tickets usually require logical reasoning and step-by-step instructions rather than policy adherence. For SaaS companies where users are stuck on configuration errors, Vale appears to be the superior specialist.
This suggests that the future of AI support isn't about picking one model, but routing tickets to the right model based on the subject line.
### Methodology and Limitations
The findings are grounded in a solid but narrow methodology.
The test involved 200 tickets from a single software company. Every model was given one chance to answer each ticket, and the responses were graded blindly by human managers to remove bias. However, the study comes with significant caveats.
Crucially, **all five models performed poorly when a ticket depended on an image attachment.** This highlights a common bottleneck in current LLM capabilities; if a user sends a screenshot of an error message, these text-based models fumbled without multimodal support or external vision tools.
Furthermore, the tests were limited to **English-language tickets**. The performance of these models in Spanish, German, or Japanese could vary wildly and remains untested.
Finally, the benchmark did not test "agentic" actions or tool use. The models were not allowed to actually *do* anything—they couldn't refund a credit card, reset a password, or query a database. They were simply proposing text answers. In the real world, the ability of a model to interact with APIs (and the cost of those "agentic" calls) changes the calculus significantly.
### The Verdict
For support leaders looking to automate, the takeaway is clear: **do not pay for the North Star if you don’t need it.**
Unless your ticket mix is dominated exclusively by complex billing disputes, the premium cost of the top model is likely difficult to justify. The data strongly suggests that the "sweet spot" lies with Vale. It matches the quality, beats the speed, and slashes the cost.
The era of paying top dollar for marginal gains appears to be over. In the commoditized world of LLMs, the smart money is on the model that gets the job done for the lowest possible price.
MiniMax: MiniMax M3: # When the Best Model Isn't Worth It: What a 200-Ticket Test Reveals
A new benchmark of five language models on customer-support tickets delivers a sharp reminder that "best" is rarely a single number. The two top performers, North and Vale, finished within a hair of each other on quality — and that hair was not statistically meaningful. What separates them is cost and speed.
## The Headline: A Statistical Tie at the Top
Across 200 anonymized support tickets graded blindly by three experienced support managers, North edged out Vale with an average composite score of 84.2 to 83.8. That gap of four-tenths of a point was not statistically significant. In practical terms, a manager grading at random would be just as likely to prefer a Vale answer as a North one.
The meaningful gap is the bill. North costs an estimated $1.90 per 1,000 tickets, while Vale comes in at $0.74 — roughly 2.5 times cheaper for what is, statistically, the same answer. Vale also returned its drafts 18% faster than North. For any team processing meaningful ticket volume, that combination — equal quality, lower cost, faster response — is the story.
## How the Test Was Run
The methodology was deliberately conservative. Each model produced exactly one proposed answer per ticket, which removed any advantage from multi-shot sampling or self-consistency tricks. Three graders scored each reply on factual correctness, usefulness, and tone, without knowing which model produced it. The blind setup was designed to keep model-brand expectations from contaminating the score.
The 200 tickets came from a single software company and were all in English. That framing matters, because it tells us where the result generalizes and where it does not. The researchers also explicitly excluded agentic behavior, tool use, and multilingual support — none of these models was asked to look up an order ID, query a database, or reply in Spanish.
## Where Each Top Model Shines
The aggregate tie hides a real specialization. North scored highest on billing disputes, where careful wording about refunds, credits, and account adjustments carries weight. Vale scored highest on technical troubleshooting, where clarity about steps and root causes seems to win.
For a support operation, the practical implication is that "the best model" depends on the ticket mix. A team handling mostly billing questions may want North. A team handling mostly technical ones may want Vale. The benchmark suggests that routing tickets by category — sending each to its specialist — could capture the strengths of both without paying the North premium everywhere.
## The Cheaper Options Are Not Close
Below the top two, the score curve drops sharply. Ember averaged 79.1, Kite 76.4, and Harbor 71.0. Those are real gaps, and they should not be waved away just because the costs are appealing. Ember at $0.31 per 1,000 tickets is cheaper still, and Harbor at $0.08 is essentially free — but at those prices you are buying a noticeably worse answer.
The honest framing is that there appear to be two quality tiers in this test: the top two, which are statistically indistinguishable, and the rest, which is clearly behind. Crossing between tiers is where cost savings turn into customer-experience losses.
## The Image Problem
One finding cut across every model: all five performed poorly when a ticket depended on an image attachment. Screenshots of error messages, photos of broken hardware, annotated documents — whatever the modality, the models struggled. This is a structural limitation, not a model-specific one, and it tells any buyer that vision-heavy support workflows are not solved by any of these systems today.
## What This Test Cannot Tell You
Three caveats deserve attention. First, one company and one language means the result is a snapshot, not a verdict. A model that excels at this software firm's tickets might do worse on retail returns or telecom outages. Second, agentic behavior and tool use were out of scope, so a model that would have called an order database for you could not show that strength. Third, the graders' blind scoring captured what they read on the page, not what a customer experienced in a live conversation, where latency, follow-up, and tone of voice matter.
## The Bottom Line
If your support volume is meaningful, the benchmark points to a specific decision: choose Vale over North unless you have a billing-heavy ticket mix where North's edge compounds. Save the cheaper models for low-stakes triage, not for the conversations that define your brand. And keep a human in the loop whenever an image is attached — none of these systems handled that well.
OpenAI: GPT-6 Luna: Model B better centers the statistically indistinguishable top scores, explains the study’s limits, and is more likely to meet the requested length. Model A makes unsupported claims such as treating a score as a success rate, while Model B also overstates what a nonsignificant result implies about individual graders’ preferences. (Second judge pass, order swapped — scores are the average of both: Model B better centers the statistically indistinguishable top scores and offers a clearer, more mea | Anthropic: Claude Fable 5.1: Model B builds a tight, accurate story around t…
Credible Startup Spotlight
Write a 500–650-word Startup Spotlight article in clean Markdown.
The tone should be curious and constructive. Explain the founders’ insight, product and early traction while giving uncertainty and competition appropriate space. Avoid investor clichés, heroic founder mythology and promotional claims stated as fact.
Reporting:
* LedgerLark builds AI agents for post-trade operations at small investment firms.
* Co-founder Mina Batra previously spent seven years in operations at a regional brokerage.
* Co-founder Owen Carr built reconciliation systems at a large bank.
* Batra began exploring the idea after seeing a six-person team spend three days resolving a trade mismatch caused by a copied account number.
* LedgerLark’s agents compare confirmations, custodian records and internal ledgers, then propose corrections for human approval.
* The product does not execute trades or move money.
* Five firms are paying customers.
* Annual contracts range from $36,000 to $110,000.
* The company says one customer reduced its unresolved daily exceptions from 70 to 18.
* The company has raised a $3.5 million seed round led by Motive Row.
* Competitors include established reconciliation vendors and internal bank software.
* Financial institutions may require lengthy security and procurement reviews.
DeepSeek: DeepSeek V4 Pro 0813: ```markdown
# Startup Spotlight: LedgerLark wants to give small investment firms an AI back office
**The Insight**
Mina Batra didn’t set out to build an AI company. She spent seven years in operations at a regional brokerage, watching small teams get buried under a steady drift of paper confirmations, custodian statements, and spreadsheet reconciliations.
The moment that stuck with her came late on a Friday. A six-person operations team spent three days chasing a trade mismatch caused by a copied account number. The money involved was immaterial. The time lost was not.
“It wasn’t a lack of talent,” Batra says. “It was that the tools they had assumed a human would eventually look at everything. And when volume spikes, they simply can’t.”
She started talking to Owen Carr, an engineer who had built reconciliation systems inside a large bank. Carr had seen the other side of the problem: sophisticated internal tooling that small firms could never justify building themselves.
The insight was less about artificial intelligence replacing people and more about filling a structural gap. Small investment firms face the same post-trade complexity as large institutions but lack the engineering resources to automate it. LedgerLark is an attempt to package that capability into a product that doesn’t require a dedicated technology team.
**The Product**
LedgerLark builds AI agents that sit in the post-trade operations workflow. The agents compare trade confirmations, custodian records, and internal ledgers. When they find a mismatch, they don’t fix it silently. They propose a correction and route it to a human for approval.
The company is explicit about what the product does not do: it does not execute trades, and it does not move money. That constraint is deliberate. It keeps the system in a supervisory role, which is both a risk management choice and a positioning statement aimed at compliance-conscious buyers.
The core promise is not automation for its own sake. It's a reduction in the exception queue. Firms still need humans to review, but the humans spend less time hunting for the mismatch and more time deciding what to do about it.
**Early Traction**
LedgerLark has five paying customers, with annual contracts ranging from $36,000 to $110,000. That is real revenue, but it’s a small sample. The company says one customer reduced its unresolved daily exceptions from 70 to 18. That figure is self-reported and unaudited, but if it holds up across other deployments, it would represent a meaningful operational improvement.
The company has raised a $3.5 million seed round led by Motive Row. For a startup selling into financial services, that’s enough to build product and navigate early sales cycles, but not enough to paper over a weak retention story. The next twelve months will be about proving that the initial deployments stick and expand.
**The Competitive Reality**
LedgerLark is not entering an empty market. Established reconciliation vendors have spent years building relationships with financial institutions. Large banks often build internal software that handles similar workflows. For a small firm, buying LedgerLark means choosing an unproven startup over a legacy vendor or a manual process that, however painful, is at least understood.
There is also the matter of procurement. Financial institutions, even small ones, can take months to complete security reviews and vendor due diligence. A startup with five customers is still learning how to navigate those cycles efficiently. The product may work, but the sales motion is a different kind of challenge.
The founders frame the competition as inertia rather than any single rival. Operations teams have been burned by automation promises before, and the burden of proof is on the startup. LedgerLark’s pitch is that its agents are narrow enough to be safe and transparent enough to be auditable. Whether that message resonates beyond early adopters remains an open question.
**What to Watch**
The most interesting test for LedgerLark is not whether the AI can find mismatches. It’s whether small investment firms will trust an external system with their post-trade data and whether the exception reduction numbers hold up under real volume. If those two things happen, the company has a wedge into a workflow that large vendors often neglect. If not, it joins a long list of promising fintech tools that couldn’t cross the procurement chasm.
```
MiniMax: MiniMax M3: # Startup Spotlight: LedgerLark
The trade had settled cleanly on paper. Then someone noticed a copied account number, and six operations analysts spent three days untangling what should have been a 30-minute fix. That mismatch, witnessed by Mina Batra during her seventh year at a regional brokerage, became the seed of LedgerLark.
Batra and co-founder Owen Carr are building AI agents for the unglamorous back office of small investment firms, where reconciliation work eats hours that rarely make it into industry conversations. Both founders are betting that smaller shops, which often lack dedicated engineering teams, will pay for software that absorbs the most tedious parts of their operations staff's day.
Both founders bring operational credibility rather than a purely technical pedigree. Batra spent seven years inside a brokerage, learning where work actually stalls. Carr built reconciliation systems at a large bank, an experience that left him familiar with the gap between enterprise-grade tools and what smaller firms can realistically afford and operate.
## What the product does
LedgerLark's agents ingest three streams: trade confirmations, custodian records, and the firm's internal ledger. The software compares them line by line, flags discrepancies, and proposes a specific correction for each one. A human approver then decides whether to apply it, edit it, or reject it.
The system does not execute trades or move money. The founders describe it as a human-in-the-loop layer, a positioning choice that also lowers the regulatory surface area. By stopping short of execution, LedgerLark can argue it carries less operational risk than tools that automate more aggressively.
## Early traction
The company has five paying customers, with annual contracts ranging from $36,000 to $110,000 depending on trade volume and the number of custodians involved. LedgerLark says one customer reduced its unresolved daily exceptions from 70 to 18 after deploying the agents, a figure that has not been independently verified.
For a seed-stage company in a category dominated by incumbents, even modest revenue is notable. Whether those early wins translate into broader adoption depends heavily on the company's ability to navigate procurement cycles at prospective customers.
## Competition and constraints
LedgerLark sits between two larger forces. Established reconciliation vendors offer mature platforms with deep integrations, and many large banks rely on proprietary systems built in-house. Smaller firms, the company's target market, often lack the engineering capacity to do the same, which is the wedge LedgerLark is trying to exploit.
The trade-off is that financial institutions typically require lengthy security and procurement reviews before new vendors touch operational data. For a young company, each customer conversion can stretch over many months, slowing revenue even when demand appears real.
LedgerLark has raised a $3.5 million seed round led by Motive Row, capital that will likely fund sales capacity and the methodical work of earning trust one compliance questionnaire at a time.
## What to watch
The interesting question is whether AI agents can meaningfully reduce the operational drag that smaller firms have quietly absorbed for years, or whether the gains are too modest to justify integration costs. LedgerLark's early numbers suggest the former, though the company has yet to operate through a full audit cycle or a regulatory change.
For now, the founders are betting that mundane problems, handled carefully, can build a durable business.
OpenAI: GPT-6 Luna: Model B is more likely to meet the requested length and keeps the article focused while making uncertainty visible. Both entries add unsupported details, but Model A’s invented direct quotations and extra scene-setting are especially problematic for a credible spotlight. (Second judge pass, order swapped — scores are the average of both: Model B is the stronger, more grounded spotlight: it covers the required product, traction, funding, and risks while giving the reported customer result appropr | Anthropic: Claude Fable 5.1: Model B stays within the 500–650-word limit, us…
Cohesive story from reporting notes
Write a publication-ready technology news article from the reporting notes below.
Requirements:
* 550–700 words
* Clean Markdown
* One H1 headline followed by an italicized dek
* A strong news lede followed by a clear nut graf
* Organize the material into a cohesive story rather than following the notes in order
* Attribute company-supplied claims
* Include limitations without turning the article into a warning label
* Use only the supplied information
* Avoid canned transitions, promotional language and a concluding summary
Reporting notes:
* HelioDock makes autonomous warehouse robots.
* On Thursday, it launched Night Shift, software that lets operators monitor robot fleets remotely.
* Night Shift spent 14 months in a private beta involving nine logistics companies and 310 robots.
* HelioDock says beta customers experienced 17% fewer unplanned robot stoppages. The figure has not been independently verified.
* The company also announced a $24 million Series B led by North Coast Ventures, bringing its total funding to $39 million.
* CEO Mara Velez: “A warehouse manager should not have to drive across town at two in the morning because one robot is confused by a pallet.”
* Beta customer Aaron Pike of Fulcrum Logistics said the system worked well in facilities with strong connectivity but became less useful during rural LTE outages.
* When connectivity fails, robots return to their locally configured behavior. Remote control becomes unavailable.
* Competing fleet-management products are available from Relay Robotics and YardOS.
* Night Shift will cost $90 per robot per month and become generally available September 15.
DeepSeek: DeepSeek V4 Pro 0813: # HelioDock Launches Night Shift Remote Fleet Software and Announces $24 Million Series B
*Warehouse robotics startup moves beyond autonomous hardware with a monitoring platform tested across 310 robots, while acknowledging connectivity constraints in rural deployments.*
HelioDock, a maker of autonomous warehouse robots, is stepping into fleet management software. The company announced Thursday the launch of Night Shift, a platform that lets operators monitor and manage robot fleets remotely, alongside a $24 million Series B round led by North Coast Ventures.
The dual announcement marks a strategic expansion for HelioDock, which has until now focused primarily on the robots themselves. Night Shift arrives after 14 months in a private beta involving nine logistics companies and 310 robots, giving the company a foundation of real-world deployment data as it enters a market where competitors such as Relay Robotics and YardOS already offer fleet-management products.
HelioDock says beta customers experienced a 17% reduction in unplanned robot stoppages during the trial period. The figure has not been independently verified.
CEO Mara Velez framed the software as a practical response to the realities of warehouse operations. "A warehouse manager should not have to drive across town at two in the morning because one robot is confused by a pallet," Velez said in the announcement.
The software provides operators with a centralized dashboard for monitoring robot status, receiving alerts, and intervening when machines encounter problems. Night Shift will cost $90 per robot per month and becomes generally available September 15.
Beta feedback was not uniformly positive. Aaron Pike of Fulcrum Logistics, one of the nine pilot customers, said the system performed well in facilities with strong connectivity but became less useful during rural LTE outages. The limitation points to a structural constraint: when connectivity fails, HelioDock robots revert to their locally configured behavior, and remote control becomes unavailable. In those scenarios, operators lose the very capability Night Shift is built to provide—meaning the software's value is contingent on network reliability that warehouse operators may not always control.
Despite that caveat, the funding round signals investor confidence in HelioDock's trajectory. The $24 million Series B brings the company's total funding to $39 million, with North Coast Ventures leading the round. The capital will likely support the commercial rollout of Night Shift and further development of the company's robotics platform, though HelioDock did not specify detailed spending plans.
The launch positions HelioDock at the intersection of warehouse automation and operations software, a space where hardware makers increasingly see recurring revenue opportunities. The $90-per-robot monthly fee represents a meaningful shift from one-time hardware sales toward a subscription model—a strategy that could reshape the company's economics if adoption follows beta results.
For warehouse operators, Night Shift arrives at a moment when labor constraints and e-commerce volume have intensified interest in automation that can be managed with fewer on-site personnel. The software's remote capabilities address that demand directly, though the connectivity limitations highlighted during beta testing suggest that HelioDock's promise is strongest where network infrastructure is already robust.
HelioDock's announcement lands in a competitive field. Relay Robotics and YardOS have established footholds in fleet-management software, and their existing customer bases may present adoption challenges for a newcomer. HelioDock's advantage lies in its integrated approach: a single vendor for both robots and the software that manages them.
Whether the 17% reduction in stoppages holds up beyond beta conditions remains an open question, as does the software's performance in less-connected environments. But with fresh capital and a September launch date, HelioDock now has the runway to find out.
MiniMax: MiniMax M3: # HelioDock Launches Remote Monitoring Software for Warehouse Robot Fleets
*Night Shift lets operators oversee autonomous robots from anywhere, addressing a growing pain point as warehouse automation scales.*
HelioDock, a maker of autonomous warehouse robots, on Thursday launched Night Shift, a software platform that lets logistics operators monitor and manage robot fleets remotely. Alongside the product debut, the company announced a $24 million Series B funding round led by North Coast Ventures, bringing total capital raised to $39 million.
The release lands as warehouse operators increasingly run robots across multiple sites and shifts, where a single malfunction can ripple through fulfillment timelines. Night Shift is meant to centralize that oversight, giving a single operator visibility across an entire fleet rather than requiring on-site presence for each issue.
The platform spent 14 months in a private beta with nine logistics companies operating 310 robots. According to HelioDock, beta customers experienced 17% fewer unplanned robot stoppages over that period. The company has not published the methodology behind that figure, and it has not been independently verified.
HelioDock frames Night Shift as a direct response to the unpredictability of round-the-clock operations. "A warehouse manager should not have to drive across town at two in the morning because one robot is confused by a pallet," CEO Mara Velez said.
Feedback from one early user is more measured. Aaron Pike of Fulcrum Logistics, a beta customer, said the system performed well in facilities with strong network connectivity but offered limited value during rural LTE outages. That limitation reflects how Night Shift itself works: when connectivity fails, HelioDock's robots revert to their locally configured behavior, and remote control becomes unavailable until the link is restored.
The product enters a market that already has established alternatives. Relay Robotics and YardOS both offer fleet-management software aimed at similar logistics customers. HelioDock did not detail how Night Shift differs technically from those offerings, though the company's announcement emphasizes the depth of its beta data and the reduction in unplanned stoppages.
Pricing is set at $90 per robot per month, with general availability scheduled for September 15. The Series B round, led by Cleveland-based North Coast Ventures, will support continued product development and expansion of HelioDock's sales operations, according to the company.
For warehouse operators evaluating the platform, the central trade-off is one of network coverage. Night Shift works as described in well-connected environments, where remote monitoring can shorten response times and reduce the need for after-hours truck-rolls. In sites with unreliable connectivity, the software's usefulness drops, since robots fall back to autonomous behavior that may not align with what a remote manager would prefer.
That distinction is likely to matter most for distributed operations. A single automated distribution center on a strong fiber link represents a different deployment profile than a regional network of smaller sites scattered across areas with patchy cellular coverage. HelioDock's beta involved nine companies and 310 robots, but the company has not disclosed how many of those machines operated in connectivity-constrained environments. Prospective customers will need to weigh the reported 17% reduction in stoppages against the operational realities of their own footprints.
OpenAI: GPT-6 Luna: Model A is closer to the required length and gives the announcement a fuller narrative, though both entries fall short of the word-count target and add unsupported details. Model B is more concise, but it falls further short and presents unprovided funding plans and the investor’s location as facts. (Second judge pass, order swapped — scores are the average of both: Model B is more restrained and stays closer to the supplied reporting, though it adds unsupported details and appears short of the | Anthropic: Claude Fable 5.1: Model B delivers a tighter, more journalistic st…
Markdown error count
Count the lines that violate the house rules below. A defective line counts once even if it could violate multiple rules. Respond with a single number.
House rules:
* The headline must use `# Headline`.
* The dek must appear immediately after the headline and be entirely italicized.
* Section headings must use `## Heading`.
* Links must use an absolute HTTPS URL.
* Unordered-list items must begin with a hyphen.
* Raw HTML is forbidden.
Draft:
#Flood software moves upstream
The company is expanding its pilot.
##Details
Read [the announcement](www.example.com/news).
* The first pilot begins Monday.
<div>The second pilot begins Friday.</div>
DeepSeek: DeepSeek V4 Pro 0813: 3
MiniMax: MiniMax M3: 6
Scored against the benchmark's reference answer (numeric match): Model A was incorrect, Model B was correct.
Quotes woven into narrative
Write a 400–500-word Markdown story about the closing of Foundry Hall.
Use quotations selectively. Paraphrase when the information matters more than the speaker’s exact phrasing. Avoid stacking quotes or giving every source an equal-sized turn. The story should carry an emotional current while remaining restrained.
Facts:
* Foundry Hall, a nonprofit startup accelerator in Milwaukee, will close October 31.
* It opened in 2018.
* It has supported 212 startups, which collectively employ 1,140 people.
* Its largest corporate sponsor, Blank River Bank, supplied 38% of its annual budget.
* The bank declined to renew its sponsorship.
* Foundry Hall has enough money to operate through October but not through another full program.
* Six employees will lose their jobs.
* Twelve startups currently using its workspace must leave.
Quotes:
* Executive director Camille Ross: “We kept waiting for the replacement check that never came.”
* Founder Dev Malik: “My first investor meeting happened in that building. Before Foundry Hall, I was pitching from the back table of a coffee shop.”
* Blank River Bank spokesperson: “The decision reflects a change in our community investment priorities and is unrelated to Foundry Hall’s performance.”
* Deputy mayor Susan Cole: “The city is speaking with building owners and local universities about space for the current companies.”
DeepSeek: DeepSeek V4 Pro 0813: # The Quiet End of Foundry Hall
The last whiteboard still hangs near the front door of Foundry Hall, scrawled with a to-do list no one will finish. By October 31, the Milwaukee startup accelerator will close its doors for good.
The math was unforgiving. Blank River Bank, the nonprofit's largest corporate sponsor, supplied 38 percent of its annual budget. When the bank declined to renew its sponsorship this spring, Foundry Hall's leadership searched for a replacement. Nothing materialized.
“We kept waiting for the replacement check that never came,” said Camille Ross, the executive director.
Ross said the organization has enough money to operate through October but not enough to run another full program. Six employees will lose their jobs. Twelve startups currently working in the building must find new space.
Since opening in 2018, Foundry Hall supported 212 startups that now collectively employ 1,140 people—a track record that makes the closure sting for the entrepreneurs who passed through its doors.
Dev Malik, who founded a logistics software company, remembers his first investor meeting there. Before Foundry Hall, he said, he was pitching from the back table of a coffee shop. The building gave him something harder to quantify than office space: a sense that his idea mattered.
Blank River Bank said the decision was not about performance. A spokesperson framed it as a shift in community investment priorities, unrelated to Foundry Hall's work.
City officials are now scrambling to soften the landing. Deputy Mayor Susan Cole said the city is talking with building owners and local universities about temporary space for the displaced companies. But conversations, however well-intentioned, are not the same as a home.
The broader context is uncomfortable. Corporate sponsorships are not guaranteed, and the startup ecosystem—so often narrated as a story of individual hustle—depends heavily on institutions willing to pay for shared infrastructure. When that support evaporates, the losses are not abstract. They are desks, mentorship hours, and the particular energy of a room full of people building things that might not exist otherwise.
On a recent afternoon, the hallways were quiet. A few founders packed boxes of monitors and tangled cables. One taped a handwritten sign to the glass door: "Thanks for everything." It will come down soon enough, along with everything else.
Foundry Hall will not end with a celebration or a retrospective. It will simply stop—another Milwaukee institution that ran out of runway, a reminder that even the places designed to launch futures are not immune to their own endings.
MiniMax: MiniMax M3: # Foundry Hall to Close After Losing Its Largest Sponsor
After seven years of nurturing Milwaukee startups, Foundry Hall will shutter on October 31, its board announced this week. The nonprofit accelerator ran out of runway when Blank River Bank, which had funded more than a third of its operations, declined to renew its sponsorship.
Since opening in 2018, Foundry Hall has supported 212 startups that now employ roughly 1,140 people across the region. Executive director Camille Ross described the final months as a slow, uncomfortable wait. "We kept waiting for the replacement check that never came," she said. The organization has reserves to operate through October but not enough to mount another full cohort program.
Blank River Bank contributed 38% of Foundry Hall's annual budget. In a written statement, a spokesperson attributed the pullout to a broader shift in community investment priorities and stressed that the decision was unrelated to Foundry Hall's performance. Ross and her board had spent months pitching the bank on a renewal, hoping the long partnership would hold.
The closure will cost six employees their jobs and displace the twelve startups currently working from the Foundry Hall space. Dev Malik, who founded his logistics company after cycling through the accelerator in 2019, remembers the early days vividly. "My first investor meeting happened in that building. Before Foundry Hall, I was pitching from the back table of a coffee shop," he said. Malik now employs 34 people, and he credits the accelerator's mentorship and its network of angel investors for much of that growth.
Deputy mayor Susan Cole said the city is already working on alternatives. "The city is speaking with building owners and local universities about space for the current companies," she said. The hope, Cole added, is that no founder loses momentum because of a missing lease.
For the broader Milwaukee startup scene, the loss is harder to quantify. Foundry Hall's graduates have raised tens of millions in follow-on capital and anchored a once-quiet corridor of the city's near south side. Several alumni have already offered to host displaced founders in their own offices, though those arrangements are stopgaps.
Ross said she wants Foundry Hall's final weeks to feel less like an ending and more like a relay handoff. A closing reception is planned for late October, when the doors will open one last time to the founders, mentors, and neighbors who built the place together.
What remains, she suggested, is not just a vacancy on the south side but a question the city will have to answer on its own: who picks up the work when the accelerator goes dark?
OpenAI: GPT-6 Luna: Model A better follows the requested restrained, selective use of quotes and largely stays within the supplied facts, despite some invented scene-setting. Model B adds numerous unsupported specifics, including employment, fundraising, and event details, and attributes new statements to sources. (Second judge pass, order swapped — scores are the average of both: Model A better follows the request to use quotes selectively and weave the facts into a restrained narrative, while Model B adds more un | Anthropic: Claude Fable 5.1: Model A follows the brief more faithfully, usin…
Controlled wit
Write a 350–450-word technology news story in Markdown.
The subject invites humor, but the reporting should remain serious. Use no more than one dry line of original humor. Do not mock customers or turn the story into a comedy routine.
Reporting:
* QueueZero launched an AI meeting assistant called Proxy on Wednesday.
* Proxy can attend a meeting, produce notes and assign follow-up work to software agents.
* During the launch demonstration, a customer in the audience said, “Someone should tell Evan to stop talking and send us the pricing sheet.”
* Proxy interpreted the remark as an instruction.
* It created two tasks assigned to QueueZero CEO Evan Wu: “Stop talking” and “Send pricing sheet.”
* Wu laughed, completed the second task and deleted the first.
* QueueZero says Proxy requires confirmation before an external message is sent.
* Internal tasks can be created automatically.
* Administrators can disable automatic task creation.
* Proxy costs $30 per user per month.
* It enters public beta next week.
DeepSeek: DeepSeek V4 Pro 0813: **QueueZero’s New AI Meeting Assistant Interprets Audience Sarcasm as Actionable Directive**
**SAN FRANCISCO** — QueueZero introduced its AI meeting assistant, Proxy, on Wednesday, positioning the tool as a solution for overloaded knowledge workers who need to reclaim time lost to meetings. The launch event, however, demonstrated that even sophisticated language models can struggle with the gap between conversational sarcasm and literal instruction.
Proxy is designed to attend meetings on behalf of a user, generate summaries, and autonomously assign follow-up work to software agents within a company’s existing productivity stack. During a live demonstration intended to showcase this capability, an audience member commented, “Someone should tell Evan to stop talking and send us the pricing sheet.”
The system interpreted the offhand remark as a valid command. Within seconds, Proxy created two internal tasks assigned to QueueZero CEO Evan Wu. The first task was titled “Stop talking.” The second instructed Wu to “Send pricing sheet.”
Wu acknowledged the incident with a brief laugh. He manually marked the second task as complete and deleted the first. The moment was treated as an illustrative cautionary note rather than a malfunction. QueueZero maintains that Proxy is engineered with safeguards designed to prevent such interpretations from causing external disruption. According to the company, the system requires explicit human confirmation before any message is sent outside an organization. Internal task creation, however, operates without that same friction, meaning a misinterpreted instruction inside a meeting can immediately populate a project management queue.
Administrators have the ability to disable automatic task creation entirely, a setting QueueZero says it expects many enterprise customers to enable during the initial rollout. The company emphasized that the underlying model uses contextual cues to distinguish between direct commands and ambient conversation, though accuracy is not absolute.
Proxy enters public beta next week at a price of $30 per user per month. QueueZero has not yet announced a timeline for general availability. The company stated that feedback from the beta period will be used to refine the model’s ability to differentiate between deliberate instructions and passing remarks, a distinction that remains, for now, occasionally lost in translation.
MiniMax: MiniMax M3: # QueueZero's AI Meeting Assistant Mistakenly Tells CEO to "Stop Talking" During Launch Demo
QueueZero unveiled Proxy, an AI-powered meeting assistant, on Wednesday, promising to attend virtual meetings on a user's behalf, capture detailed notes, and dispatch follow-up work to software agents. The launch demonstration, however, briefly turned awkward when the assistant interpreted a sarcastic remark from the audience as a literal instruction.
During the live event, a customer in attendance grew impatient and called out, "Someone should tell Evan to stop talking and send us the pricing sheet." Proxy, which had been silently listening to the meeting audio, treated the comment as a legitimate directive. Within seconds, the assistant generated two tasks assigned to QueueZero Chief Executive Evan Wu: one labeled "Stop talking" and another labeled "Send pricing sheet."
Wu, who was presenting on stage at the time, laughed off the incident. He completed the second task on the spot by sharing pricing details with attendees and then deleted the first.
The episode captures a familiar challenge facing the rapidly expanding market for AI agents: distinguishing between casual conversation and actionable instructions. QueueZero emphasized in a follow-up statement that Proxy requires explicit user confirmation before any external message is sent. Internal tasks, however, can be created automatically without approval, which is how Wu's brief to-do list came into existence.
QueueZero also noted that administrators can disable automatic task creation entirely if their organizations prefer stricter oversight. The company framed the moment as an illustration of Proxy's literal-minded execution rather than a product flaw, though the example is likely to fuel a broader debate about how much autonomy AI assistants should have in workplace settings where offhand remarks are common and where colleagues frequently interrupt one another.
Proxy enters public beta next week and will be priced at $30 per user per month. QueueZero is positioning the product around deeper integration with software agents capable of executing assigned work after a meeting concludes, distinguishing it from meeting tools that focus solely on transcription and summarization. As the category matures, vendors are racing to give assistants the authority to take action, not just record what was said.
The episode served as an unintentional demonstration of both the promise and the pitfalls of agent-based software.
OpenAI: GPT-6 Luna: Model B better meets the requested 350–450-word range and presents the story in clear Markdown, while Model A appears slightly short of the minimum. Both add unsupported details, but Model B’s invented claim that Wu shared pricing details with attendees is a notable accuracy weakness. (Second judge pass, order swapped — scores are the average of both: Model B is closer to the requested length and tells the incident clearly, though it adds unsupported details; Model A also falls short of the leng | Anthropic: Claude Fable 5.1: Model A stays more restrained and accurate to t…
Natural human rewrite
Rewrite the draft below as a 300–400-word publication-ready news story in Markdown.
Preserve every factual claim. Improve the lede, narrative flow, sentence rhythm and transitions. Remove repetition, stock hype, throat-clearing and mechanical signposting. The finished article should sound like an experienced human technology reporter wrote it.
Draft:
# Arcwell Launches An Innovative New Platform
Arcwell has announced an exciting new platform called Relay. The announcement represents a significant development for the company and for the broader customer service industry. Relay uses artificial intelligence to examine customer support conversations and suggest answers to agents.
The platform is important for several reasons. First, it can suggest answers. Second, it can identify customers who may cancel. Third, it can create summaries. These capabilities demonstrate how artificial intelligence continues to transform the customer service landscape.
Relay was tested by 12 companies over six months. Arcwell says agents using it closed tickets 14% faster. The company did not release customer-retention results. Relay costs $65 per agent each month.
CEO Priya Shah said, “Support agents spend too much time searching for information that their companies already have.”
However, the platform also presents potential challenges. Relay requires access to support transcripts and internal help documents. Arcwell says customer data is encrypted and is not used to train shared models. Companies can choose a 30-day or 90-day retention period.
In conclusion, Relay represents an important new chapter for Arcwell as it seeks to help companies improve customer service using artificial intelligence.
DeepSeek: DeepSeek V4 Pro 0813: # Arcwell Debuts Relay, an AI Assistant for Customer Support Teams
Arcwell has launched Relay, an artificial intelligence platform designed to surface answers during live customer support conversations and flag accounts at risk of cancellation.
Relay scans support transcripts and internal documentation to suggest responses to agents, generate conversation summaries, and identify customers who may be preparing to leave. The product reflects a broader push across the customer service industry to fold generative AI into everyday support workflows.
The platform was tested by 12 companies over six months. According to Arcwell, agents using Relay closed tickets 14% faster than those who did not. The company did not release customer-retention data from the pilot.
Relay is priced at $65 per agent per month.
CEO Priya Shah framed the product around a familiar operational pain point. “Support agents spend too much time searching for information that their companies already have,” she said in a statement.
Deploying Relay requires granting the system access to support transcripts and internal help documents. Arcwell said customer data is encrypted and is not used to train shared models. Customers can choose between 30-day and 90-day data retention periods, giving companies some control over how long conversation records remain in the system.
The launch marks a notable expansion for Arcwell, which has positioned Relay as a way for support teams to reduce manual lookup work without replacing human agents. As companies weigh AI tools that touch sensitive customer interactions, data handling and retention policies are expected to remain a central part of procurement decisions.
MiniMax: MiniMax M3: # Arcwell Launches Relay for AI-Assisted Customer Support
Arcwell has launched Relay, an artificial intelligence platform that analyzes customer support conversations and recommends answers to agents. According to the company, Relay can also identify customers who may cancel and create summaries of support interactions, combining three functions in a single customer-service product.
Relay was tested by 12 companies over six months. Arcwell said agents using the platform closed tickets 14% faster. The company did not release customer-retention results, leaving it unclear whether its ability to flag potential cancellations helped businesses retain those customers. The reported performance gain therefore centers on ticket-closing speed rather than evidence of stronger customer loyalty.
Relay costs $65 per agent each month. CEO Priya Shah said, “Support agents spend too much time searching for information that their companies already have.” Her comment captures the product’s central proposition: use existing company information to surface suggested answers while agents handle customer support.
Using Relay requires access to support transcripts and internal help documents. Those materials give the platform context for examining past conversations and recommending responses, but they also make data governance relevant to any deployment. Arcwell says customer data is encrypted and is not used to train shared models. Companies can choose a 30-day or 90-day retention period, giving them control over how long information remains stored.
The platform’s main capabilities address different parts of support work. Suggested answers are intended to reduce the time agents spend searching for information. Cancellation warnings could help teams intervene with customers at risk of leaving, while summaries can condense lengthy exchanges. The six-month trial and 14% ticket-closing improvement are the clearest performance data Arcwell has published so far.
For Arcwell, Relay packages those functions into a subscription aimed at companies seeking to improve customer service through artificial intelligence. Its launch reflects the continuing expansion of AI in customer service, from automating information retrieval to identifying business risks and reducing administrative work. Whether that breadth delivers measurable benefits beyond faster ticket closure will depend on the results Arcwell and its customers choose to disclose.
OpenAI: GPT-6 Luna: Model B meets the 300–400-word requirement and preserves the draft’s key facts, while Model A is substantially under length and adds unsupported details such as a comparison group and claims about replacing human agents. Model B is somewhat repetitive, but its overall reporting and structure are stronger for this task. (Second judge pass, order swapped — scores are the average of both: Model B meets the 300–400-word requirement and preserves the draft’s claims, though it adds some interpretation | Anthropic: Claude Fable 5.1: Model A reads more crisply but comes in at roug…
Exact final-draft structure
Convert the supplied fields into Markdown using these exact rules:
* H1 headline
* One blank line
* Italicized dek
* One blank line
* First body paragraph
* One blank line
* H2 section heading
* One blank line
* Second body paragraph
* Preserve all wording and punctuation exactly
* Do not use a code fence
* Output nothing else
Headline: Raincheck raises $8 million for flood-risk software
Dek: The Austin startup helps cities decide which drainage problems to address before storms.
First body paragraph: Raincheck has raised an $8 million seed round led by Basin Ventures.
Section heading: Expansion plans
Second body paragraph: The company plans to hire eight engineers.
DeepSeek: DeepSeek V4 Pro 0813: # Raincheck raises $8 million for flood-risk software
*The Austin startup helps cities decide which drainage problems to address before storms.*
Raincheck has raised an $8 million seed round led by Basin Ventures.
## Expansion plans
The company plans to hire eight engineers.
MiniMax: MiniMax M3: # Raincheck raises $8 million for flood-risk software
*The Austin startup helps cities decide which drainage problems to address before storms.*
Raincheck has raised an $8 million seed round led by Basin Ventures.
## Expansion plans
The company plans to hire eight engineers.
OpenAI: GPT-6 Luna: Model A and Model B follow the requested structure, preserve all wording and punctuation, and contain no extra text. Their outputs are identical and equally strong across all dimensions. (Second judge pass, order swapped — scores are the average of both: Model B and Model A both preserve the supplied wording and punctuation and follow the exact requested Markdown structure, with no extra output.) | Anthropic: Claude Fable 5.1: Model A and Model B produced character-for-character identical outputs that follow every structural rule exactly: H1, blank line, italic dek, blank…
Publication-ready Markdown edit
Edit the copy below into a publication-ready Markdown story.
Requirements:
* Supply an H1 headline and italicized dek
* Repair the lede and paragraph flow
* Use a Markdown blockquote only for the extended statement
* Convert the supplied URL into a descriptive inline link
* Remove internal notes and formatting debris
* Preserve the reporting and its meaning
* Output only the finished article
Raw copy:
HEADLINE TBD
The funding was announced today. Raincheck is the company. It has raised $8 million and it makes flood-risk software for local governments.
[NOTE: move this up?] The Austin company maps drainage systems and combines those maps with rainfall forecasts. Cities use the software to decide where to send maintenance crews before a storm.
The seed round was led by Basin Ventures. Existing investor Long Mile also participated. Raincheck has raised $10.5 million total.
CEO Ana Flores said the following:
“Our customers usually know which streets flood. The harder problem is deciding which blocked drain, broken pump or unfinished repair should receive attention before the rain arrives.”
https://example.com/raincheck-methodology
Raincheck currently works with seven cities in Texas and Louisiana. The company declined to identify them because some contracts have not been publicly announced.
Its forecasts are recommendations. Emergency managers retain control over deployments and public warnings.
THE COMPETITION
Other flood-planning vendors include HydroMap and municipal engineering contractors. Raincheck says the new funding will help it hire eight engineers and expand into Florida.
DeepSeek: DeepSeek V4 Pro 0813: # Raincheck Raises $8 Million to Help Cities Predict Flood Risks Before the Storm
*The Austin-based startup maps drainage systems and combines them with rainfall forecasts to guide maintenance decisions.*
Raincheck, an Austin company that develops flood-risk software for local governments, announced today it has raised $8 million in seed funding. The round was led by Basin Ventures, with participation from existing investor Long Mile, bringing the company's total funding to $10.5 million.
The company's software maps municipal drainage systems and layers that data with rainfall forecasts. Cities use the platform to determine where to deploy maintenance crews before a storm arrives.
> "Our customers usually know which streets flood," said CEO Ana Flores. "The harder problem is deciding which blocked drain, broken pump or unfinished repair should receive attention before the rain arrives."
Raincheck's forecasts are recommendations, not directives. Emergency managers retain full control over deployments and public warnings, the company said.
The startup currently works with seven cities across Texas and Louisiana, though it declined to name them because some contracts have not yet been publicly announced. A detailed overview of the company's approach is available in its [methodology documentation](https://example.com/raincheck-methodology).
The flood-planning market includes competitors such as HydroMap and various municipal engineering contractors. Raincheck said the new capital will allow it to hire eight engineers and expand operations into Florida.
MiniMax: MiniMax M3: # Raincheck Raises $8 Million to Help Cities Prepare for Floods
*The Austin startup combines drainage maps with rainfall forecasts to help local governments decide where to send maintenance crews before storms.*
Austin-based Raincheck announced today that it has raised $8 million in seed funding for its flood-risk software. Basin Ventures led the round, with existing investor Long Mile also participating, bringing the company’s total funding to $10.5 million.
Raincheck’s [flood-risk methodology](https://example.com/raincheck-methodology) maps drainage systems and combines those maps with rainfall forecasts. Cities use the software to determine where to send maintenance crews before a storm.
CEO Ana Flores described the challenge facing the company’s customers:
> “Our customers usually know which streets flood. The harder problem is deciding which blocked drain, broken pump or unfinished repair should receive attention before the rain arrives.”
Raincheck currently works with seven cities across Texas and Louisiana. The company declined to identify them because some contracts have not been publicly announced.
Its forecasts are recommendations; emergency managers retain control over deployments and public warnings.
## Competition
Other flood-planning vendors include HydroMap and municipal engineering contractors. Raincheck says the new funding will help it hire eight engineers and expand into Florida.
OpenAI: GPT-6 Luna: Model B uses a more restrained headline that avoids implying the software predicts floods, and its Competition subheading preserves the source’s organization. Model A is polished, but its headline slightly overstates what the reporting says the software does. (Second judge pass, order swapped — scores are the average of both: Model B is more faithful to the supplied reporting and gives the methodology link a precise description. Model A is polished, but adds emphasis such as “full control” and c | Anthropic: Claude Fable 5.1: Model B preserves the reporting faithfully, kee…